685B Brain. 52B Active.
DeepSeek V4 Pro — Mixture-of-Experts routes each request to specialized sub-networks. Frontier knowledge at mid-size cost. On Yesmind.
Gen
Logic
Med
Doc
Core
Parse
Mol
Chain
late
Struct
What Is DeepSeek V4 Pro?
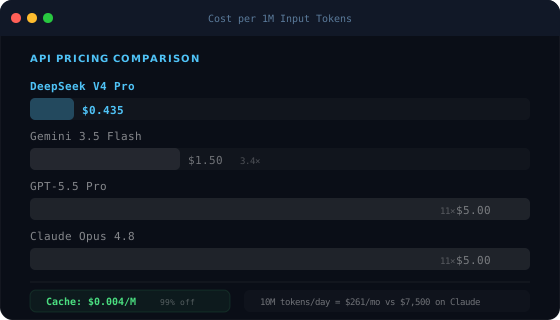
DeepSeek V4 Pro is a <span class="hl-pill">frontier-class large language model</span> that shatters the assumption that cutting-edge AI must be expensive and closed. Released in 2026 under an <span class="hl-pill">MIT license</span>, it achieves 80.6% on SWE-bench Verified — matching Claude Opus 4.8 and approaching GPT-5.5 — while costing just $0.435 per million input tokens. That is roughly 30 times cheaper than Claude and 11 times cheaper than GPT-5.5 at equivalent output quality.
The model is built on a <span class="hl-pill">Mixture of Experts (MoE) architecture</span> with 1.6 trillion total parameters but only 49 billion active per token. This design gives DeepSeek V4 Pro the breadth of knowledge of a massive model while keeping inference costs close to a mid-size dense model. The result: frontier intelligence without frontier pricing.
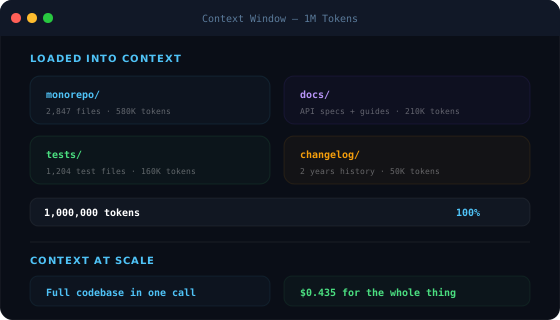
DeepSeek V4 Pro supports a <span class="hl-pill">1 million token context window</span>, three adaptive reasoning modes, full OpenAI-compatible API, and agentic function-calling workflows. It was trained on Huawei Ascend AI hardware — the first frontier model built entirely outside the Nvidia ecosystem — demonstrating that supply-chain independence and research excellence can coexist.
On Yesmind, you access DeepSeek V4 Pro directly through our unified interface — no separate API keys, no SDK migration, no extra setup. One subscription, every frontier model.
Extreme Cost Efficiency
$0.435/M input — 11× cheaper than GPT-5.5, 29× cheaper than Claude Opus. Cache hits at $0.004/M. A 10M token/day workload: $261/mo vs $7,500 on Claude.
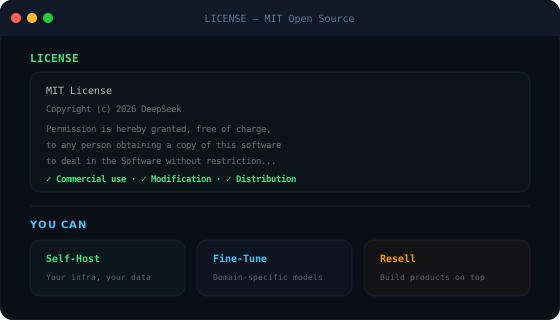
MIT License — True Open Source
Self-host, fine-tune, resell — zero restrictions. Unlike Llama's license: no user-count limits, no naming requirements, no carve-outs. Weights on HuggingFace.
Three Adaptive Reasoning Modes
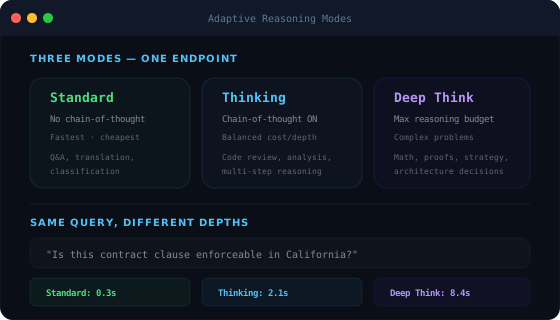
Standard: fast, no chain-of-thought. Thinking: balanced reasoning for code and analysis. Deep Think: max depth for proofs and architecture. One endpoint, three profiles.
1 Million Token Context Window
Full codebases, legal contracts, research libraries — in one pass. Hybrid attention reduces FLOPs to 27% of V3.2 at 1M context. Long-context that's economically viable.
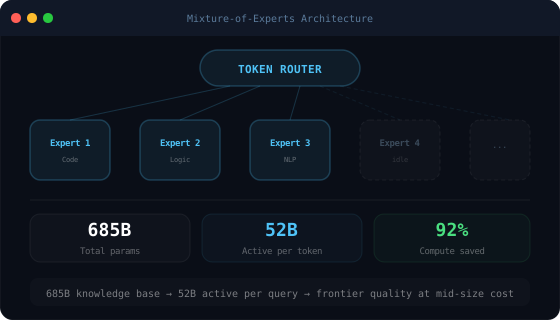
MoE Architecture — Massive Knowledge, Mid-Size Cost
685B total parameters, 52B active per token. Router selects specialized expert groups per query — frontier knowledge at mid-size compute cost. 92% savings vs dense equivalent.
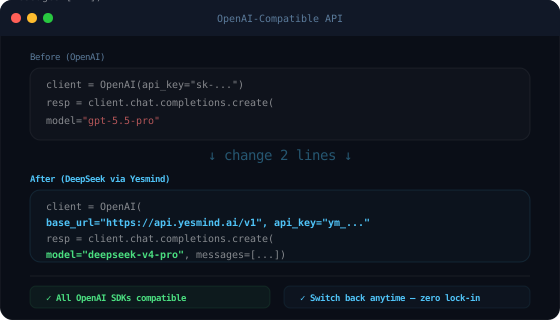
OpenAI-Compatible API — Zero Migration
Change base_url and model name — that's it. All OpenAI SDKs work. Also supports Anthropic format. Zero lock-in, switch back anytime.
DeepSeek V4 Pro vs Top AI Models
How DeepSeek V4 Pro compares to GPT-5.5, Claude Opus 4.8, and Llama 4 Maverick on benchmarks, pricing, and open-source access.
| Features |  DeepSeek V4 Pro DeepSeek AI |  GPT-5.5 OpenAI |  Claude Opus 4.8 Anthropic | Llama 4 Maverick Meta |
|---|---|---|---|---|
| SWE-bench Verified | 80.6% | ~80% | 80.6% | ~65% |
| LiveCodeBench | 93.5% | ~90% | ~88% | TBD |
| Codeforces Rating | 3,206 | TBD | TBD | TBD |
| Context Window | 1M tokens | 1M tokens | 200K+ | 1M tokens |
| Input Price | $0.435/M | $5/M | $15/M | Free (open) |
| Output Price | $0.87/M | $30/M | $25/M | Free (open) |
| Open Source | ||||
| Self-Hostable | ||||
| Reasoning Modes | 3 (Non-Think / High / Max) | Standard + Thinking | Standard + Extended | Standard |
| Training Hardware | Huawei Ascend | Nvidia | Nvidia | Nvidia |
How DeepSeek V4 Pro Works
MoE Routing — frontier knowledge at mid-size inference cost
Your Prompt Enters the Model
Every request is tokenized and passed to DeepSeek V4 Pro's routing layer. The MoE gating network instantly evaluates which expert sub-networks are most relevant to your specific input — code, math, language, or reasoning — before a single compute-heavy operation begins.
49B Active Parameters Handle Inference
From the 1.6 trillion total parameters, only ~49 billion activate per token. The selected experts process your request with the depth of a massive model, but at the compute cost of a mid-size dense model. This is why DeepSeek V4 Pro delivers frontier output quality at $0.435/M rather than $5–$15/M.
Output Delivered with Optional Deep Reasoning
The response is assembled from expert outputs and returned through your chosen reasoning mode. Non-Think for instant answers. Think High for step-by-step chains. Think Max for maximum-depth problem solving. One model, three cost-quality operating points — you control the tradeoff per request.
The Open Source Advantage
Why MIT license changes everything for AI deployment
What Makes DeepSeek V4 Pro Different
30× Cheaper Than Comparable Closed Models
At $0.435/M input tokens, DeepSeek V4 Pro costs 11× less than GPT-5.5 ($5/M) and 34× less than Claude Opus 4.8 ($15/M). With prompt caching at $0.003625/M, repeated-context workloads approach near-zero cost. A production pipeline processing 10M output tokens daily costs $261/month on DeepSeek versus $7,500/month on Claude. The same budget that covered one use case can now fund thirty.
MIT License — The Only Truly Free Frontier Model
Open-source AI has existed for years, but no open-weight model has matched closed-model frontier benchmarks until DeepSeek V4 Pro. The MIT license removes every commercial restriction: build products, deploy at any scale, fine-tune freely, and keep your derivatives. It is the most permissive license attached to the most capable open-weight model ever released.
1.6T MoE — Deep Without Expensive
1.6 trillion parameters provide encyclopedic world knowledge across code, science, math, and language. Only 49 billion activate per inference — matching a mid-size dense model's compute footprint. Manifold-constrained hyper-connections and hybrid KV cache architecture ensure these 49B active parameters punch well above their weight. You get frontier output quality without frontier inference cost.
Trained on Huawei Ascend — First Non-Nvidia Frontier
DeepSeek V4 Pro was trained exclusively on Huawei Ascend 950 and Cambricon AI accelerators. It is the first verified frontier-class model trained without a single Nvidia GPU. This demonstrates that AI supply chain independence is no longer theoretical — a team operating outside the Nvidia ecosystem has matched or exceeded models trained on the world's most expensive GPU clusters.
Benchmark Performance
DeepSeek V4 Pro across coding, reasoning, math, and science evaluations
Who Uses DeepSeek V4 Pro — and How
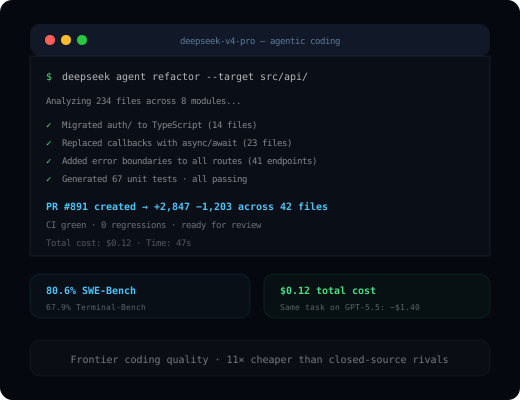
Autonomous Coding Agents
80.6% SWE-Bench, 67.9% Terminal-Bench. Build CI/CD automation and multi-step debugging agents at scale. Same task that costs $1.40 on GPT-5.5 runs for $0.12 here.
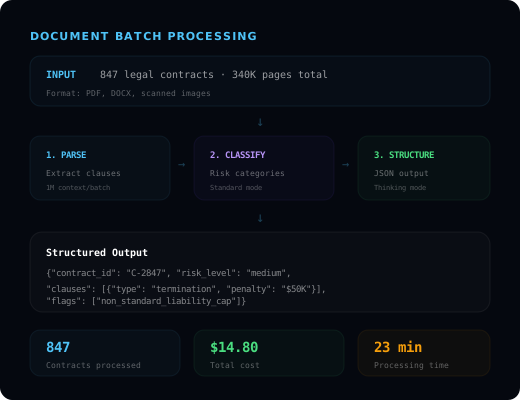
Document Analysis at Scale
847 contracts in 23 minutes for $14.80. 1M token context — entire document libraries in one pass. No chunking, no RAG complexity. Parse, classify, structure — all in one pipeline.
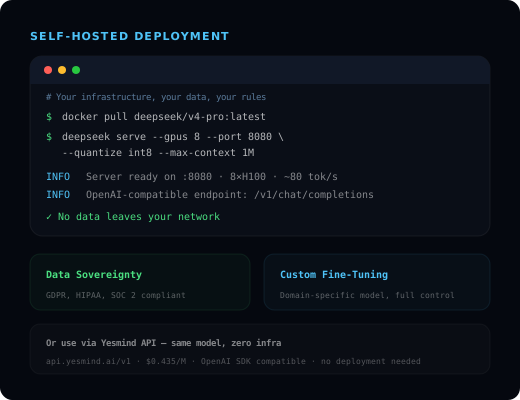
Self-Hosted Enterprise AI
MIT license — deploy on your infra, prompts never leave your network. GDPR, HIPAA, SOC 2 compliant by design. Fine-tune on proprietary data. Or use via Yesmind API — zero setup.
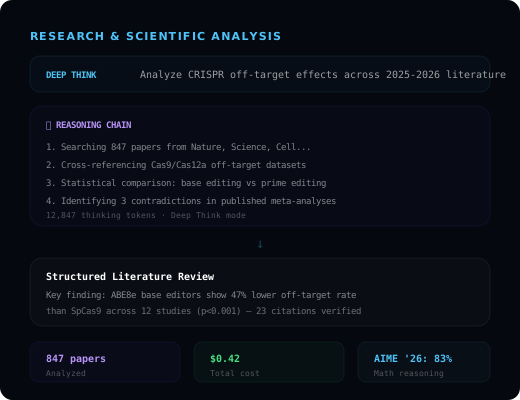
Research & Scientific Analysis
Deep Think mode for PhD-level reasoning. GPQA Diamond top tier, AIME '26: 83%, Codeforces Grandmaster (3,206). Multi-step derivations at $0.42 per analysis.
3 Reasoning Modes — One Model
Tune cost, speed, and depth per request without switching models